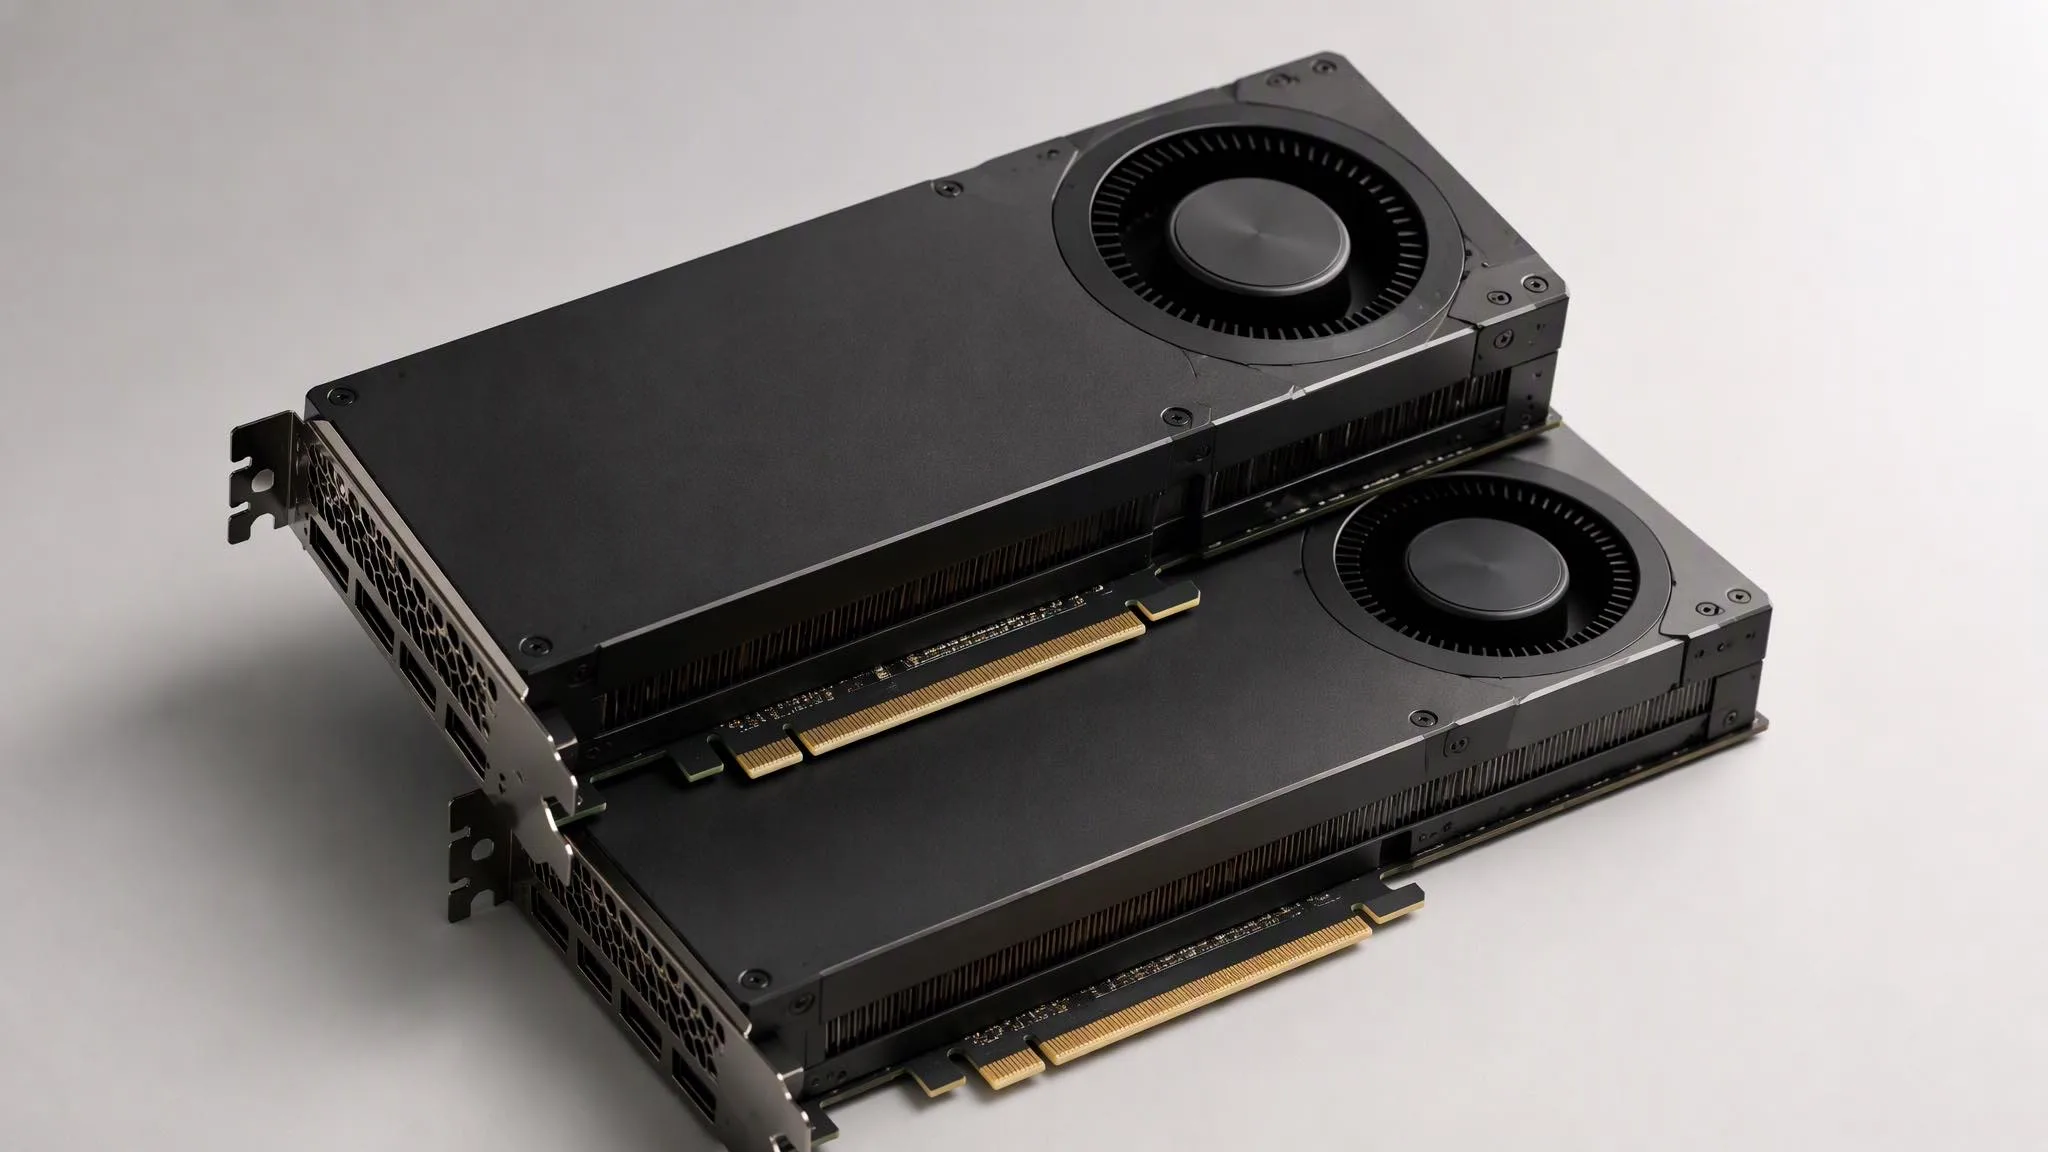
Data-Center GPU
Product line 06 / 06 — Live stock list

Data-Center GPU Wholesale

Wholesale data-center GPUs — NVIDIA Blackwell and Hopper (B200, H200, H100), Ada Lovelace inference cards (L40S, L40, L4) and AMD Instinct MI300-series accelerators, new and tested pulls, with platform compatibility guidance.

Graphics cards for servers are data-centre GPUs that accelerate AI training, inference, HPC and virtual desktop workloads. Huazhe Server supplies NVIDIA Blackwell B200, Hopper H200 and H100, Ada Lovelace L40S and L4 accelerators, and AMD Instinct MI300X / MI250X GPUs — wholesale quantities, new factory-sealed or pulled-and-tested with thermal stress reports for AI labs and integrators.

30SKUs in stock list
12New condition
18Pulled & tested
24hQuote turnaround
PDF
Data-Center GPU Stock List — SEP 2026 (PDF)Full part-number list with condition & remarks · updated monthly
Download PDF
Featured models

In-demand part numbers

A selection from the current stock list — filter by model or paste a part number. Can't find yours? Download the full list or send a BOM; we source hard-to-find parts.

AI Training — Blackwell & Hopper

B200 / H200 / H100 / H800 / H20 · SXM / PCIe · new & HGX pulls

7 featured −
ModelVRAMTDPFormPart No.Cond
NVIDIA B200Blackwell · Flagship trainingHBM3e 192GB~1000WGB100 SXMOn board labelNEWQuote →
NVIDIA H200Hopper · HGX H200HBM3e 141GB700WGH100 SXM5900-21010-0200-000NEWQuote →
NVIDIA H200 NVLHopper · NVLink bridge pairHBM3e 141GB600WGH100 PCIe Gen5900-21010-0040-000NEWQuote →
NVIDIA H100 80GB SXM5Hopper · HGX H100 pullHBM3 80GB700WGH100 SXM5900-21010-0000-000USEDQuote →
NVIDIA H100 80GB PCIeHopper · OEM tray avail.HBM3 80GB350WGH100 PCIe Gen5900-21010-0900-000USEDQuote →
NVIDIA H800 80GB PCIeHopper · CN market · NVH800HBM3 80GB350WGH100 PCIe Gen5900-21010-0010-000USEDQuote →
NVIDIA H20 96GB PCIeHopper · CN marketHBM3 96GB400WGH100 PCIe Gen5On board labelNEWQuote →

AI / HPC — Ampere Refurbished

A100 / A800 HGX and PCIe variants · tested

5 featured +
ModelVRAMTDPFormPart No.Cond
NVIDIA A100 80GB PCIeAmpereHBM2e 80GB300WGA100 PCIe Gen4900-21001-0014-000USEDQuote →
NVIDIA A100 80GB SXM4Ampere · HGX A100 pullHBM2e 80GB400WGA100 SXM4900-21001-0040-000USEDQuote →
NVIDIA A100 40GB PCIeAmpereHBM2 40GB250WGA100 PCIe Gen4900-21001-0000-003USEDQuote →
NVIDIA A100 40GB SXM4AmpereHBM2 40GB400WGA100 SXM4900-21001-0030-100USEDQuote →
NVIDIA A800 80GB PCIeAmpere · CN marketHBM2e 80GB300WGA100 PCIe Gen4On board labelUSEDQuote →

Inference & VDI — New

L40S / L40 / L4 / A40 / A10 / A30 / RTX 6000 Ada · MIG & vGPU

7 featured +
ModelVRAMTDPFormPart No.Cond
NVIDIA A30 24GB PCIeAmpere · 4 MIG instancesHBM2 24GB165WGA100 PCIe Gen4699-21001-0205NEWQuote →
NVIDIA L40SAda Lovelace · Inference flagshipGDDR6 48GB350WAD102 PCIe Gen4900-2G133-0080-000NEWQuote →
NVIDIA L40Ada Lovelace · vGPU certifiedGDDR6 48GB300WAD102 PCIe Gen4900-2G133-0010-000NEWQuote →
NVIDIA L4Ada Lovelace · Low profile · 72WGDDR6 24GB72WAD104 PCIe Gen4900-2G193-0000-000NEWQuote →
NVIDIA RTX 6000 Ada 48GAda Lovelace · Workstation / VDIGDDR6 48GB300WAD102 PCIe Gen4900-5G133-2250-000NEWQuote →
NVIDIA A40Ampere · NVLink 2-wayGDDR6 48GB300WGA102 PCIe Gen4900-2G133-0000-000NEWQuote →
NVIDIA A10Ampere · vGPU / VDIGDDR6 24GB150WGA102 PCIe Gen4900-2G133-0020-000NEWQuote →

Workstation & Budget Pulls

RTX 4090 / 3090 / A6000 / T4 / V100 / P40 · tested

7 featured +
ModelVRAMTDPFormPart No.Cond
NVIDIA RTX 4090 24GBAda Lovelace · Consumer / AIGDDR6X 24GB450WAD102 PCIe Gen4On board labelUSEDQuote →
NVIDIA Tesla T4 16GBTuring · Low profile · 70WGDDR6 16GB70WTU104 PCIe Gen3900-2G183-0000-000USEDQuote →
NVIDIA RTX A6000 48GBAmpere · Quadro lineageGDDR6 48GB300WGA102 PCIe Gen4900-5G133-2200-000USEDQuote →
NVIDIA RTX 3090 24GBAmpere · Consumer / AIGDDR6X 24GB350WGA102 PCIe Gen4On board labelUSEDQuote →
NVIDIA V100 32GB SXM2Volta · HGX V100 pullHBM2 32GB300WGV100 SXM2On board labelUSEDQuote →
NVIDIA V100 16GB PCIeVoltaHBM2 16GB250WGV100 PCIe Gen3On board labelUSEDQuote →
NVIDIA Tesla P40 24GBPascal · Inference budgetGDDR5 24GB250WGP102 PCIe Gen3On board labelUSEDQuote →

AMD Instinct

CDNA 3 / 2 / 1 accelerators · OAM & PCIe

4 featured +
ModelVRAMTDPFormPart No.Cond
AMD Instinct MI300XCDNA 3 · Flagship OAMHBM3 192GB750W3 OAMOn board labelNEWQuote →
AMD Instinct MI250XCDNA 2 · Aldebaran · Dual-die OAMHBM2e 128GB560W2 OAMOn board labelUSEDQuote →
AMD Instinct MI210CDNA 2 · Aldebaran · ROCm stackHBM2e 64GB300WAldebaran PCIe Gen4100-000000419USEDQuote →
AMD Instinct MI100CDNA 1 · Arcturus · LegacyHBM2 32GB300WArcturus PCIe Gen4On board labelUSEDQuote →
Before you order
  • SXM / OAM modules are baseboard-bound (HGX / UBB) and are not standalone PCIe cards — verify tray and baseboard compatibility before quoting.
  • Used units: GPU hours, ECC error counts and thermal service history are recorded per batch and disclosed on request.
  • Multiple board variants exist per model (CEC / non-CEC, OEM-specific) — confirm the exact 900-number on the board label. Quotes are valid for 7 business days by default; the validity stated on the quotation takes precedence.
Buyer's notes

How to buy Data-Center GPU in bulk

Two notes cover how to buy data-center GPUs in bulk. The selection guide starts from the workload: model size and batch concurrency set the VRAM requirement — 48 GB on the L40S, 141 GB on the H200, 192 GB on the MI300X — while training versus inference decides how much memory bandwidth you need, and PCIe versus SXM follows your chassis, power and cooling envelope; export-control restrictions are flagged at quotation stage. The condition-grades note compares factory-sealed new against pulled-and-tested cards: what our sustained thermal stress reports disclose per batch, why GPU pulls hold their value better than other components, and how serial-list verification before payment filters grey-market and remarked stock. Read both before committing AI budget — then run the five checks in our used-GPU verification guide (GPU hours, ECC history, sustained thermals, serial traceability, OEM-platform load test) on any batch quote you receive. The SEP 2026 stock list PDF above lists every card with VRAM, TDP, form factor and part number — download it, then send your node specification for a 24-hour quotation.

How to choose a data-center GPU

Start from the workload. Model size and batch concurrency set the VRAM requirement — 48 GB on the L40S, 141 GB on the H200, 192 GB on the MI300X — and training versus inference decides how much HBM bandwidth you actually need. Inference fleets often get better value from more, smaller cards than from fewer flagships.

Choose the form factor next. SXM and OAM modules are baseboard-bound for HGX and UBB platforms and are not electrically or mechanically standalone cards; standard servers take PCIe variants — H100 PCIe, H200 NVL, L40S, L4 or MI210. Confirming tray and baseboard compatibility up front prevents the most expensive mismatch in GPU procurement.

Check the power and cooling envelope before ordering: 700 W SXM parts need the right manifold and PSU headroom, and dense PCIe builds need confirmed airflow. For 8-GPU nodes we kit the complete baseboard, host CPUs, memory, storage and NICs as one BOM with one warranty window.

Budget the fabric with the silicon — NVLink and NVSwitch topologies and InfiniBand east-west networks change the node design — and note that export-control rules apply to some SKUs and destinations. We flag restrictions at quotation stage and offer compliant alternatives where a part cannot ship.

Data-center GPU condition grades: new vs pulled vs refurbished

New factory-sealed cards carry the factory warranty — the right call for production training clusters where downtime costs more than silicon, and where the platform vendor's support terms require sealed provenance.

Pulled & tested cards are stress-tested on OEM platforms with sustained thermal validation, which catches cooling and power-delivery problems a short bench run misses. Per batch we record and disclose GPU hours, ECC error history and thermals, and tested pulls carry our up-to-2-year coverage with advance replacement for critical spares. Many AI labs mix grades across one cluster — new for the production training fabric, pulls for inference and dev pools.

GPU pulls depreciate less than other components — typically 20–40% below new rather than half price — because inference demand keeps the floor high. Bargain-basement pricing on current-generation parts is itself a warning sign.

Refurbished GPUs on the broker market range from honest pulls to remarked cards, and traceable serials are the filter. Ask for the serial list before payment and walk away from any seller who will not provide one; we disclose provenance documentation with every order.

GradeSourceTestingShips withBest forPrice vs new
New — factory sealedDistribution / OEM channelsManufacturer QAFactory warranty, provenance docsProduction training clustersReference price
Pulled & testedDecommissioned AI / cloud nodesSustained thermal + stress test on OEM platformsGPU hours, ECC history, thermals per batch; serial list before paymentInference fleets, dev pools, mixed clustersTypically 20–40% below
RefurbishedBroker market — quality varies widelyVerify serials with vendor; remarking is commonProvenance + serial traceability requiredOnly with verified provenanceVaries — beware outliers
Used AI GPUs: how to verify, grade and source data-center cards in bulk
FAQ

Data-Center GPU — answers before you ask

The questions procurement teams ask first. Anything else — WhatsApp is fastest.

No — SXM and OAM modules are baseboard-bound for HGX and UBB platforms and are not electrically or mechanically standalone cards. For standard servers we quote PCIe variants instead: H100 PCIe, H200 NVL, L40S, L4 or AMD MI210. Confirming tray and baseboard compatibility up front prevents the most expensive mismatch in GPU procurement.

Per batch we record GPU hours, ECC error history and thermals, then stress-test units on OEM platforms before dispatch, and the report ships with your order. Sustained thermal validation catches cooling and power-delivery problems that a short bench run misses. New cards carry factory warranty; tested pulls carry our up-to-2-year coverage with advance replacement for critical spares.

Yes — we kit complete HGX baseboards with the SXM GPUs, host CPUs, memory, NVMe storage and high-speed NICs as a single BOM, so you deal with one quotation, one test report and one shipment. Send the node specification — GPU model and count, CPU, memory, storage — and the consolidated quote comes back within 24 hours with a single warranty window across the node.

Sample units for platform validation are available on request, and every unit ships with recorded GPU hours, ECC error history and stress-test results, so the sample is representative of the batch. Ask for the serial list before payment — traceable serials are the fastest way to filter out grey-market or remarked cards, and we disclose provenance documentation with every order.

Yes — new factory-sealed cards and pulled-and-tested units are stocked side by side, and many AI labs mix both grades across a cluster to hit budget. Used units are stress-tested on OEM platforms with GPU hours, ECC error counts and thermal history disclosed per batch. Export-control restrictions on some SKUs and destinations are flagged at quotation stage, with compliant alternatives offered where a part cannot ship.
—— Request for quotation

Send the BOM.
We quote in 24h.

Availability, pricing and lead time from a named engineer — inside one business day.